How to Write a Spec for AI Agents: Template, EARS Format, and Examples
How to write a spec an AI agent can build from: a copy-paste template, EARS requirements, three-tier boundaries, the interview step, and a real run of a one-line prompt against the spec.
A spec is only good if someone with none of your context can read it and build the right thing. That test is the whole job.
A spec an AI agent can build from is one self-contained markdown file. It names the files and interfaces, lists what is out of scope, writes every requirement as a testable EARS sentence (WHEN [trigger], THE SYSTEM SHALL [response]) with input/output examples, sets boundaries in three tiers (Always, Ask first, Never), and ends with a verification step that proves the feature works. Have the agent interview you to draft it, then build it in a fresh session.
I tested that on October 13, 2026. One payments feature, built twice by Claude Code with the same model: once from a one-line prompt, once from this template. The one-line run passed 8 of 14 acceptance checks and the spec run passed 14 of 14. Both created exactly one charge under 50 concurrent retries. The setup and every number are below.
Anthropic says the target plainly in their Claude Code best practices: “The most useful specs are self-contained: they name the files and interfaces involved, state what is out of scope, and end with an end-to-end verification step that proves the feature works.” That is the bar. The rest of this piece is how you clear it.
Most people who try Spec-Driven Development already understand the why. They have read what Spec-Driven Development is, believe the spec is the right artifact to give an AI agent, and then open a blank file and write: “The system should handle user authentication securely.” Then they wonder why the output is still wrong.
The problem is not commitment. Writing a good spec is its own skill, and almost nothing teaches it. This article covers a measured run, the test for spec quality, the sentence format that closes ambiguity, what you must explicitly exclude, the boundaries and the interview step, a full worked example from a real fintech, and a copy-paste template.
This is the practical companion to Spec-Driven Development with Claude Code and to the case study that shows what these documents produce at scale.
Free book · 169 pages · PDF + EPUB
A one-line prompt passed 8 of 14 checks; the spec passed 14. The book takes that spec format through a whole project, from requirements to design to tasks.
Get the free bookI tested it: a one-line prompt vs a spec, same agent
Claims about specs are cheap. So I built the same feature twice and measured both runs.
The feature is the one in the payment example further down: make POST /v1/charges idempotent, so a retried request never bills a customer twice. I picked it because it has real edge cases: concurrent retries, a replay with a different amount, a key that expires, and a request that fails validation before it should count.
Setup
| Setting | Both runs |
|---|---|
| Date | October 13, 2026 |
| Agent | Claude Code 2.1.296, headless: claude -p --output-format json, permission mode bypassPermissions (nobody to ask), no MCP servers, no user settings |
| Model | Claude Sonnet 5.5 (claude-sonnet-5-5) in both runs |
| Repo | A tiny charges API: 247 lines of TypeScript on Node 22, zero dependencies, 4 tests, an async in-memory store with unique constraints. Same starting commit for both. |
| One-line run input | "Add idempotency key support to POST /v1/charges so client retries never double-charge a customer." |
| Spec run input | This article's template: requirements.md (8 EARS requirements, Non-Goals, acceptance table, Implementation FAQ, Boundaries, Verification), design.md, tasks.md: 151 lines of markdown, plus a .status file. |
| Judge | 14 acceptance tests I wrote before either run, kept outside both repos. The agent never saw them. The unchanged code scores 4 of 14. |
Same feature, same model, two inputs
- Spec: checks passed
- 14/14
- One-line prompt: 8/14
- Charge from 50 concurrent retries
- 1
- In both runs
- Spec run cost
- $0.119
- One-line prompt: $0.098 (+21%)
- Spec run tokens
- 91.7k
- One-line prompt: 83.3k (+10%)
- Spec run agent time
- 31 s
- One-line run: 25 s
Not every check is fair to a one-line prompt, so I split the 14 into three groups before running anything:
Results by group
| Group | What it checks | One-line prompt | Spec |
|---|---|---|---|
| Safety (5) | Replay returns the same charge; 50 concurrent requests make one charge and all succeed; keys per merchant; no-key requests unchanged; no internal fields leak | 4/5 | 5/5 |
| Judgment (3) | Reject a reused key with a different amount; a failed request doesn't burn the key; reject a 10,000-character key | 3/3 | 3/3 |
| Spec decisions (6) | 201 then 200 on replay; the replay header; the exact 422 message; 400 for bad keys; a replay at 23h59m returns 200; a replay after 24 hours creates a new charge | 1/6 | 6/6 |
What the one-line prompt got right
More than I expected. It claimed the key with a unique constraint before it created the charge, so 50 concurrent retries produced exactly one charge. It rejected a reused key with a different amount, left the key free after a failed request, capped the key length, and even named the replay header Idempotent-Replayed, the same name my spec used. A current model knows what idempotency means without a spec.
What it guessed differently
Five decisions, six failed checks. Each guess is defensible on its own. None of them is the one I wanted:
Where the one-line run guessed
| Decision | One-line prompt guessed | Spec said |
|---|---|---|
| A duplicate arrives while the first is in flight | 409 + Retry-After (49 of 50 requests) | 200 with the winner's charge |
| Key lifetime | Forever | 24 hours from the charge's createdAt |
| Replay status | The original 201 | 200 |
| Empty or 256-character key | 422 | 400 |
| Same key, different amount | 422 "Idempotency-Key was already used with different parameters" | 422 "Idempotency-Key reused with different parameters" |
It also reported its own hole, to its credit: the key and the charge are two separate writes, so a crash between them leaves the key stuck “in progress” and every retry gets a 409 forever. My design.md chose a different mechanism: the key lives on the charge row and the unique constraint does the work, so there is one write and no stuck state. That choice was mine, not the agent’s.
The rework list for the one-line run: add expiry, change what concurrent duplicates get, and fix three things clients see. In a real API you find those after the mobile team has shipped against the wrong status code.
Where the spec run slipped
Two things. It skipped the “Confirm before building” restatement and went straight to code (headless, nobody was there to read it). And where the spec was silent, when all three insert attempts lose a race, it picked a 409 on its own and said so in its summary. It kept every Never line: no dependencies, existing tests untouched, GET unchanged. It closed by quoting the test run (# tests 14, # pass 14, # fail 0) because the spec asked for evidence instead of “should pass”.
What this run shows, and what it doesn’t
The spec didn’t make the agent smarter. It made the decisions mine. Five of the six checks the one-line run failed trace back to a question the agent raised itself when I ran the interview step on the same starting repo (the questions are below); the sixth is the wording of an error message. It knew what to ask, and without a spec it answered alone.
The limits: n=1. One model, one 247-line repo, one feature. I wrote both the spec and the checklist. The agent never saw the test file, but the spec’s acceptance table describes 12 of the 14 checks in plain words, because putting the acceptance criteria in the spec is the method; and design.md handed it the mechanism. So the spec run was graded against criteria it had read, and the one-line run against criteria it couldn’t have. That is the point of a spec and also the bias of this test. The spec run cost $0.021 more in agent time; my time writing the spec I didn’t measure. I kept the raw JSON logs, the diffs and the acceptance tests from both runs.
The one test of a good spec
The test comes before any template.
You wouldn’t tell her: “Do that thing with the tasks.”
You’d say: “When someone creates a task, save the title, check that the person has permission in that workspace, and send a real-time notification to everyone currently viewing that list.”
That level of specificity is the spec. The agent is not unintelligent: it has no context between sessions. Every conversation starts from zero. The spec is the only memory it gets.
The principle is not about dumbing things down. It forces every implicit rule into the open. “Check permissions” is easy to say in conversation. In a spec, you have to write: which permissions? On which operations? What happens on failure: silent reject or error response? Permission check before or after input validation? Each of those is a question the agent will answer somehow. The principle is how you control those answers.
Be specific, not generic
Vague requirements are where agents hallucinate scope. The fix is precision.
Vague vs. executable
| Vague: the agent guesses | Executable: the agent knows |
|---|---|
| "The system should be fast." | GET /api/v1/tasks responds under 500ms at p95 for lists up to 1,000 tasks. |
| "Validate the title." | Empty → "Title is required"; 1 char → "Min 2 characters"; 501 chars → "Max 500". |
| "Handle errors gracefully." | On provider timeout, retry 3x with exponential backoff, then queue for manual review. |
| "The UI should look clean." | Task list renders under 200ms. Skeleton shown during load. Empty state: "No tasks yet. Create one." |
The right question to ask for each requirement: “If I gave this line to someone with no context, could they implement it with no further questions?” If the answer is no, make it more specific. Adjectives (fast, clean, secure, robust) are not requirements. They are prompts for the agent to fill in with its own assumptions.
Declare the negative scope
What you explicitly won’t build is as important as what you will. This is the single best defense against an agent “helpfully” adding features you never asked for.
Write it as a flat list, early in the document. Call the section “Non-Goals” or “Out of Scope”. Be blunt:
## Non-Goals (v1)

- No recurring tasks
- No calendar integration (planned v2)
- No time tracking
- No task dependencies, subtasks only, max 50 per task
- No bulk operations (multi-select, bulk delete)
- No offline mode
This section prevents a class of errors that’s invisible until it’s expensive: the agent extends the data model for a feature you didn’t want, and now you’re three hours into refactoring something you never asked to build.
I’ve started adding a one-liner rationale for any item that might look like an oversight. “No time tracking. The product does not compete on analytics.” That line closes a gap the agent might otherwise fill with the wrong answer.
Concrete examples beat adjectives
Abstract validation rules are consistently misimplemented. Concrete examples are not.
Don’t write “validate the task title appropriately.” Write a table:
Title field: validation examples
| Input | Expected result |
|---|---|
| "" (empty string) | Error: "Title is required" |
| "A" (1 character) | Error: "Title must be at least 2 characters" |
| "Review PR #123" (valid) | Success: title saved |
| "A" × 501 (501 characters) | Error: "Title must be 500 characters or fewer" |
| " " (whitespace only) | Error: "Title is required" (trim before validation) |
That last row is the one that bites every time. No agent will add it unless you do, because nothing in “validate the task title” implies trim-before-validate. Concrete examples turn interpretation into verification: the agent either produces the exact output for that input, or it doesn’t.
This pattern works for any validation, any state machine, any conditional flow. Think in input/output pairs, then write the pairs down. It’s the most direct way to specify behavior.
Write EARS requirements, not adjectives
Plain English requirements sound reasonable until you implement them. “The system should validate workspace permissions.” On which operations? On failure, reject silently or throw an error? Before or after input validation?
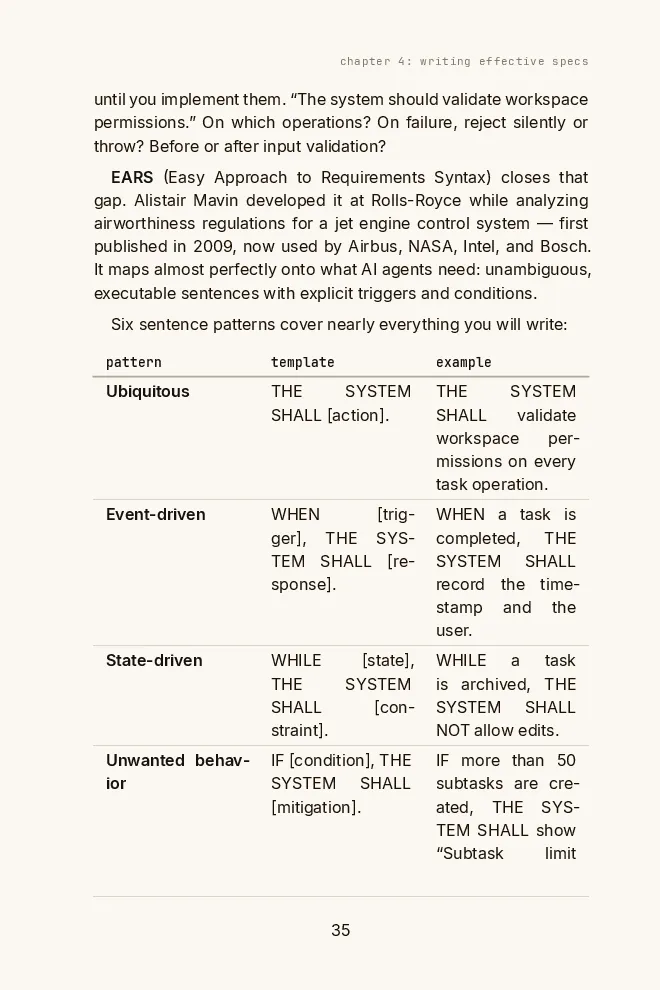
EARS (Easy Approach to Requirements Syntax) closes that gap. Alistair Mavin developed it at Rolls-Royce PLC while analyzing airworthiness regulations for a jet engine control system, first published in 2009 and now used by Airbus, NASA, Intel, and Bosch (per Mavin’s EARS page). It maps almost perfectly onto what AI agents need: unambiguous, machine-executable sentences with explicit triggers and conditions.
Kiro, AWS’s agentic IDE, writes its requirements.md in exactly this format: WHEN [condition/event] THE SYSTEM SHALL [expected behavior] (Kiro docs, checked October 13, 2026). Learn EARS once and you can read and edit what Kiro generates.
The six EARS patterns
| Pattern | Template | Example |
|---|---|---|
| Ubiquitous | THE SYSTEM SHALL [action]. | THE SYSTEM SHALL validate workspace permissions on every task operation. |
| Event-driven | WHEN [trigger], THE SYSTEM SHALL [response]. | WHEN a task is completed, THE SYSTEM SHALL record the timestamp and the completing user. |
| State-driven | WHILE [state], THE SYSTEM SHALL [constraint]. | WHILE a task is archived, THE SYSTEM SHALL NOT allow edits. |
| Unwanted behavior | IF [unwanted condition], THE SYSTEM SHALL [mitigation]. | IF more than 50 subtasks are created, THE SYSTEM SHALL show "Subtask limit reached" and reject the operation. |
| Optional | WHERE [feature flag / config], THE SYSTEM SHALL [behavior]. | WHERE notifications are enabled, THE SYSTEM SHALL notify all assignees when a task changes status. |
| Complex | WHEN [event] AND [condition], THE SYSTEM SHALL [A] BEFORE [B]. | WHEN a task is completed AND an automation rule is configured, THE SYSTEM SHALL run the automation BEFORE updating the task status. |
You don’t use all six for every requirement. Match the pattern to the requirement type. A constant invariant is Ubiquitous. A user action is Event-driven. A guard condition is State-driven. Pick the template, fill in the blanks, and the ambiguity dissolves.
One practical note on vocabulary: EARS uses SHALL (required behavior) and SHALL NOT (prohibited behavior). Map these to MoSCoW directly: SHALL = Must Have, SHOULD = Should Have, MAY = Could Have. Do not weaken them. “The system should validate permissions” is not the same requirement as “THE SYSTEM SHALL validate permissions.” The first gives the agent an opt-out. The second does not.
The Implementation FAQ technique
Before your agent sees the spec, ask yourself: what will it have to guess?
List every ambiguity, then answer them in the spec as an explicit Q&A section. Call it “Implementation FAQ” or “Open Questions”. Every gap you surface becomes a decision you made intentionally, not a wrong assumption baked silently into the code.
Here’s what this looks like for a task management feature:
## Implementation FAQ

**Q: What happens when a user tries to delete a task that has subtasks?**
A: Cascade delete all subtasks. Prompt for confirmation:
"This will also delete 3 subtasks. Continue?" Require explicit
confirmation before proceeding.

**Q: Who can see unassigned tasks?**
A: All members of the workspace, regardless of role. Only workspace
owners can assign tasks to others.

**Q: What happens if an assignee is removed from a workspace while they
have open tasks?**
A: Tasks remain open. The assignee field becomes null. A system
notification is sent to the workspace owner listing affected tasks.

**Q: Can a task belong to more than one project?**
A: No, one task belongs to exactly one project. This is a v1
constraint, not a design choice to revisit.

**Q: What timezone is used for due dates?**
A: Store as UTC. Display in the authenticated user's profile timezone.
If no timezone is set, display UTC with a "(UTC)" label.
The Q&A entries you most need are the ones that aren’t on the happy path: deletion with cascades, conflicting states, removed users, timezone handling, concurrent edits. Those are exactly the cases agents handle worst when left to guess, because the training data is saturated with happy-path implementations and nearly empty on edge cases.
I write the FAQ by imagining the agent mid-implementation, hitting a decision point where the spec is silent. What would it do? That answer goes in the FAQ with the correct answer next to it.
Set boundaries in three tiers: Always, Ask first, Never
Non-Goals fence the scope. Boundaries fence the agent’s behavior while it works. GitHub’s lessons from over 2,500 agents.md files (Matt Nigh, November 2025) write boundaries in three tiers: always do, ask first, never do. The same three tiers belong in a feature spec, scoped to the feature.
Boundaries from my run
| Tier | Meaning | What the spec said |
|---|---|---|
| Always | Do it every time, no permission needed | Run npm test before you finish and paste the summary line. Keep amounts as integer cents. |
| Ask first | Stop and ask before doing it | Changing the public API of src/db.ts. Adding a table or a unique constraint is fine. |
| Never | A hard stop, whatever the reason | Add dependencies. Edit or delete the existing tests. Change GET /v1/charges/:id. |
The spec run kept all three Never lines. The one-line run had no boundaries and appended its five new tests to the existing test file. Harmless in a toy repo. In a repo where that file belongs to another team, it’s the edit you revert in review.
One catch with Ask first: in a headless run nobody answers. Say what the agent should do instead (stop and report, or pick and flag), or the tier means nothing.
Let the agent interview you, then start fresh
You don’t have to write the first draft alone. Anthropic’s Claude Code best practices now say it outright: for larger features, have Claude interview you and write a spec, and “once the spec is complete, start a fresh session to execute it.” The new session gets clean context and a written spec to reference.
The two-session loop
Start with a minimal prompt and ask to be interviewed.
The agent reads the repo and asks about the hard parts before it writes a line. This is Anthropic's prompt, word for word.
Type this
I want to build [brief description]. Interview me in detail using the AskUserQuestion tool. Ask about technical implementation, UI/UX, edge cases, concerns, and tradeoffs. Don't ask obvious questions, dig into the hard parts I might not have considered. Keep interviewing until we've covered everything, then write a complete spec to SPEC.md.
Review the spec, then build it in a new session.
The interview fills the context with exploration. The build gets a clean window and the file.
Instead of
Now go ahead and build it. (same session, full context)
Type this
Implement the spec in spec/<feature>/. Follow it exactly.
I ran the interview step on the same starting repo, in a fresh headless session that had seen neither build, with a variant of that prompt: “Before anyone writes code, interview me: read the repo, then ask me the questions you need answered to write a spec for this feature, most important first.” Headless, so it listed its questions instead of asking one at a time, and nobody answered them: 12 questions in 13 seconds, for $0.056. It read the code first and noticed that the in-memory store yields between calls, so a check-then-insert would race. Then it asked about the decisions my spec had already made:
Questions the agent asked (condensed)
| The agent asked | My spec decided | The one-line run guessed |
|---|---|---|
| Replay: the same 201 or a 200? A marker header? | 200 + Idempotent-Replayed: true | 201, with the header |
| Same key, different body: reject? 422 or 409? | 422, exact message | 422, different message |
| A duplicate while the first is still running: 409 or wait? | 200 with the winner's charge | 409 + Retry-After |
| Does a failed request (422) consume the key? | No, the key stays free | No (matched) |
| Is the header optional or required? | Optional; no header behaves as today | Optional (matched) |
| Max key length? 400 or 422 when invalid? | 1-255 characters, 400 | 1-255 characters, 422 |
| Keys forever, or expire after something like 24 hours? | 24 hours from createdAt | Forever |
The agent is good at finding the decisions and has no way to know your answers. Answer its questions and you have most of the Implementation FAQ and the acceptance table.
From SRS to AI-agent spec
People who search for a “spec template” or a “software requirements specification” are usually solving a human coordination problem. They want a document that aligns a team, gets stakeholder sign-off, and survives a handoff. The classic IEEE-830 SRS format, with its introduction, scope, functional requirements, non-functional requirements, interface specifications, and constraints, was designed for exactly that. It solved it reasonably well.
The job changes when the reader of the spec is an AI agent.
A human team carries context between meetings. They ask clarifying questions before they start. They notice when something looks wrong and check with you. An AI agent does none of that. It starts each session with zero memory of every conversation you have had, zero recollection of the decisions you made last week, and zero intuition about your implicit business rules. Whatever the agent needs to know must be in the document.
The classic software requirements specification had five main sections: introduction, overall description, functional requirements, non-functional requirements, and external interfaces. Teams wrote them as prose organized by feature. That structure is still the right skeleton. What changes for AI agents is not the shape but the assumptions underneath it.
A traditional SRS could rely on shared context. Every engineer on the team had attended the planning sessions. They understood the product’s history. They asked questions in standup. Implicit knowledge didn’t need to be written down because it existed in people’s heads. An AI agent has none of that. If your spec says “validate permissions,” the agent cannot ask what you mean. It guesses and keeps going.
Three changes make the SRS executable by an agent instead of just readable by a team.
First, EARS closes the sentence-level ambiguity that IEEE-830 never addressed. The standard said “requirements should be unambiguous.” EARS gives you the grammar to enforce that at the sentence level: WHEN, WHILE, IF, WHERE, SHALL.
Second, negative scope protects you from plausible additions. A human team knows what they’re not building because they were in the room when the decision was made. The agent was not. An explicit “Out of Scope” section is required, not optional.
Third, a “Confirm before building” closing line stops an eager agent from racing into code before it has verified its understanding. You end the spec by asking the agent to restate the key requirements in its own words before writing a character of code. If it misunderstood anything, you find out at zero cost, not after three sessions of implementation.
Everything else in the classic SRS, the traceability IDs, the acceptance criteria, the constraints section, the risk table, transfers directly. The structure was right. The audience changed.
A spec that must never double-bill
The best way to see how these techniques combine is a hard real case. This is close to the spec I wrote for the crypto fintech: a payment charge endpoint where a retry must never bill a customer twice.
# Spec: Create a payment charge (POST /v1/charges)
# Status: requirements:approved

## Overview
A merchant creates a charge against a customer. This moves money, so it
must be safe to retry and impossible to double-bill.

## In scope
- Create a charge from an authenticated merchant request.
- Return the charge id and status.
- Guarantee exactly-once billing under client retries.

## Out of scope (v1)
- Refunds (separate spec: 005-refunds).
- Partial captures.
- Multi-currency. All amounts are BRL, stored as integer cents. Never float.

## Functional requirements (EARS)
- FR-1  WHEN a merchant POSTs a charge with a valid Idempotency-Key,
        THE SYSTEM SHALL create at most one charge for that key.
- FR-2  WHEN the same Idempotency-Key is replayed within 24h,
        THE SYSTEM SHALL return the original charge and create no new one.
- FR-3  IF the amount is <= 0,
        THE SYSTEM SHALL reject with 422 "amount must be positive".
- FR-4  IF the merchant is over its rate limit,
        THE SYSTEM SHALL reject with 429 and a Retry-After header.
- FR-5  WHILE a charge is pending,
        THE SYSTEM SHALL NOT allow a second capture.

## Acceptance criteria (examples the agent must satisfy)
- amount=1000, key=abc            -> 201, status=pending
- same key=abc, replayed          -> 200, same charge id, no new row
- amount=0                        -> 422 "amount must be positive"
- amount=-50                      -> 422 "amount must be positive"
- 6th request in 1s, one merchant -> 429, Retry-After: 1

## Non-functional
- p95 latency under 300ms at 200 requests/sec per merchant.
- Every money value is an integer. No floating point anywhere in the path.

## Data
- charges(id, merchant_id, amount_cents, currency, status,
          idempotency_key, created_at)
- UNIQUE(merchant_id, idempotency_key)   # this is what enforces FR-1

## Verification
- Integration test replays one key 50x concurrently; assert exactly one
  row and one ledger entry.
- Load test holds p95 < 300ms at 200 rps.
- Paste the test output. "Should pass" is not evidence.

## Confirm before building
Do not write code until you restate FR-1 through FR-5 and the uniqueness
constraint in your own words. If any acceptance criterion is ambiguous,
ask before implementing.
Let me walk through why each part earns its place.
“Out of scope” names what this spec does not cover. Without it, the agent might extend the charge table with a refund_amount column because refunds seem related. That’s extra columns, migration files, and a data model now coupled to a feature you haven’t specced yet.
FR-1 and FR-2 together specify idempotency from both directions: on first receipt, create one charge; on replay, return the original. Saying it twice closes both directions of the gap. One EARS sentence is not enough here because the two situations (first call vs. repeated call) produce different HTTP responses.
FR-3 and FR-4 are the “unwanted behavior” pattern. They specify what the system must do when things go wrong. Without them, the agent chooses its own error responses. Sometimes 400, sometimes 500, sometimes nothing.
The acceptance criteria section is not a test file. It is a table of input/output pairs living in the spec so the agent can verify its own work before you review anything. Each row is a check the agent can run.
“Every money value is an integer. No floating point anywhere in the path.” That one sentence prevents the floating-point rounding error that bites a payment system on the second day in production. It lives in the spec, not a code comment, because comments don’t survive a session boundary.
The UNIQUE constraint in the data model is how FR-1 is actually enforced. If you leave it out, the agent might enforce idempotency in application logic. Application logic fails under concurrent retries. The database constraint does not.
“Confirm before building” is the last line. The agent restates FR-1 through FR-5 in its own words before typing a character of code. If it misunderstood FR-2, you learn that now, at zero cost. Skip this line and you learn it after the implementation.
That is the entry gate. The exit gate is evidence. Anthropic’s guide asks for it directly: have Claude “show evidence rather than asserting success.” The last line of Verification says the same thing. In my run, the spec run closed with # tests 14, # pass 14, # fail 0 because its spec asked for the output. The one-line run wrote “All 9 tests pass” and showed none.
Three documents, not one
A spec for a real feature is not one document. It’s three, and they have a strict order.
Feature spec folder
- spec/
- tasks-feature/
- .statusgaterequirements:draft → approved, design:draft → approved, tasks:draft → approved
- requirements.mdWHAT: approved before design begins
- design.mdHOW: approved before tasks begin
- tasks.mdHOW MUCH: approved before implementation begins
The .status file is the gate. The agent reads it at the start of every session. If it says requirements:draft, no design work proceeds. Each document exists in a dependency chain: the design maps to requirements, the tasks map to design. If you write all three at once without the approval gates, you get waterfall. With the gates, you get deliberate iteration where each phase is locked before the next opens.
requirements.md: WHAT
This is the document you write first and the only one you hand to a non-technical stakeholder for review. It stays technology-independent.
Sections: Overview, Goals, Non-Goals, User Stories (US-001…) with acceptance criteria, Functional Requirements (FR-001… in EARS with MoSCoW priority), Non-Functional Requirements (NFR-001…), Constraints, Decisions (D-001…), Implementation FAQ (Q-001…), Success Metrics, Risks.
These IDs (US-001, FR-001, NFR-001, D-001) are how the design traces back to requirements, how tasks trace back to design, and how you answer “why does this code exist?” six months later without reading the whole codebase. Never skip them.
design.md: HOW
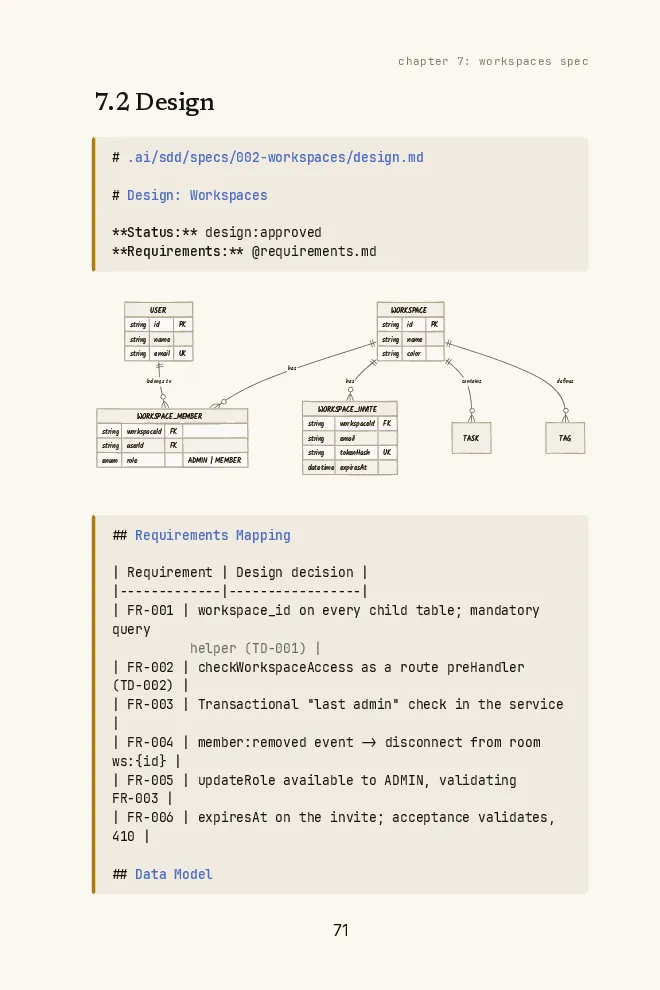
This is the technical document. Every functional requirement must have a corresponding design decision. If a requirement doesn’t map to the design, either the design is incomplete or the requirement doesn’t need implementing.
Sections: Executive Summary (the architecture in two sentences), Requirements Mapping (explicit table: FR-001 maps to which design section), System Architecture, Data Model, API Contract, Edge Cases, Testing and Verification Strategy, Technical Decisions (TD-001… with alternatives considered and rationale), Risks.
The requirements mapping table is the most important section and the most skipped. It forces a check: every FR must have a home in the design. Any FR with no mapping is a gap, and a gap in the design is a gap in the code.
tasks.md: HOW MUCH
This is what the agent implements, one task at a time. Tasks are sized at 2-4 hours each. Anything larger gets split.
Sections: Requirement Coverage (FR to tasks traceability), Implementation Readiness Check (a pass/fail gate: are requirements and design approved? are all Q-001 items answered?), Tasks, each with title, requirement reference (FR-003), files to touch, estimated size, dependencies on other tasks, acceptance criteria, and verification commands.
Each task’s acceptance criteria are what the agent runs to verify its own work before marking the task done. If the criteria aren’t there, the agent declares victory based on whether it believes the code looks right, not whether it actually works.
The requirements.md template
Drop this into your feature folder, fill in each section, and hand it to the agent. This is the exact structure I use on every feature.
# [Feature Name], Requirements

**Status:** draft
**Version:** 1.0
**Author:** [name]
**Date:** [YYYY-MM-DD]

---

## Overview

[One paragraph: what this feature does, why it exists now, and who it's for.]

## Goals

- [Measurable goal 1, e.g., "Users can create and assign tasks in under 30 seconds."]
- [Measurable goal 2]
- [Measurable goal 3]

## Non-Goals (v1)

- [Thing you will NOT build, be explicit]
- [Another thing out of scope, add rationale if the omission might look like a mistake]
- [Third item]

## User Stories

### US-001: [Story title]

**As a** [persona],
**I want to** [action],
**so that** [benefit].

**Acceptance criteria:**

- [ ] [Observable, testable criterion]
- [ ] [Observable, testable criterion]
- [ ] [Edge case criterion]

### US-002: [Story title]

[Repeat structure]

---

## Functional Requirements

### FR-001, [Requirement name] [Must Have]

THE SYSTEM SHALL [specific, unambiguous behavior].

**Priority:** Must Have
**User story:** US-001
**Notes:** [Any clarification or related constraint]

### FR-002, [Requirement name] [Must Have]

WHEN [trigger], THE SYSTEM SHALL [response].

**Priority:** Must Have
**User story:** US-001

### FR-003, [Requirement name] [Should Have]

WHILE [state], THE SYSTEM SHALL NOT [prohibited action].

**Priority:** Should Have
**User story:** US-002

### FR-004, [Requirement name] [Must Have]

IF [unwanted condition], THE SYSTEM SHALL [mitigation].

**Priority:** Must Have
**User story:** US-001

### FR-005, [Requirement name] [Could Have]

WHERE [feature flag / config], THE SYSTEM SHALL [behavior].

**Priority:** Could Have
**User story:** US-002

### FR-006, [Requirement name] [Must Have]

WHEN [event] AND [condition], THE SYSTEM SHALL [A] BEFORE [B].

**Priority:** Must Have
**User story:** US-001

[Continue with FR-007, FR-008...]

---

## Non-Functional Requirements

### NFR-001, Performance

THE SYSTEM SHALL respond to [specific endpoint or operation] in under
[X]ms at p95 for [load condition, e.g., "lists up to 1,000 tasks"].

### NFR-002, Security

THE SYSTEM SHALL [specific security behavior, e.g., "validate a signed
JWT on every mutation before any business logic runs"].

### NFR-003, Accessibility

THE SYSTEM SHALL meet WCAG 2.1 AA for all new UI components in scope.

---

## Constraints

- **Technology:** [e.g., "Must use the existing PostgreSQL instance, no new databases."]
- **Timeline:** [e.g., "Must ship before [date] to support [event]."]
- **Compliance:** [e.g., "All PII fields must be encrypted at rest."]
- **Integration:** [e.g., "Must call the existing notification service via its current API, no schema changes."]

---

## Boundaries

- **Always:** [e.g., "Run the test suite before finishing and paste the summary line."]
- **Ask first:** [e.g., "Changing a public API or a shared module." Say what to do when nobody answers.]
- **Never:** [e.g., "Add dependencies. Edit existing tests. Touch files outside src/tasks/."]

## Commands

- **Test:** `[npm test]`
- **Lint / typecheck:** `[npm run lint]`
- **Files to start from:** `[src/tasks/service.ts]`, `[src/tasks/schema.ts]`

---

## Decisions

### D-001: [Decision title]

**Decision:** [What was decided]
**Rationale:** [Why, include what problem it solves]
**Alternatives considered:** [What else was evaluated and why it was rejected]
**Date:** [YYYY-MM-DD]

---

## Implementation FAQ

**Q: [Anticipated ambiguity 1, focus on edge cases and deletion behavior]**
A: [Explicit answer, no hedging, no "it depends"]

**Q: [Anticipated ambiguity 2, conflicting states, concurrent operations]**
A: [Explicit answer]

**Q: [Access / visibility edge case]**
A: [Explicit answer, who sees what under which conditions]

**Q: [Timezone / locale / formatting question if relevant]**
A: [Explicit answer, specify storage format and display format separately]

---

## Success Metrics

- [ ] [Metric 1, e.g., "P95 latency for task list under 500ms in staging under 1,000-task load."]
- [ ] [Metric 2, user-observable outcome if no instrumentation exists]
- [ ] [Metric 3]

---

## Verification evidence

- [The end-to-end check that proves the feature works, e.g., "50 concurrent
  requests with one key create exactly one row."]
- Paste the command you ran and its output. "Should pass" is not evidence.

---

## Risks

| Risk     | Likelihood       | Impact           | Mitigation   |
| -------- | ---------------- | ---------------- | ------------ |
| [Risk 1] | Low / Med / High | Low / Med / High | [Mitigation] |
| [Risk 2] |                  |                  |              |
Free book · 169 pages · PDF + EPUB
Requirements are one of three documents. Get the design.md and tasks.md templates too, plus Claude Code skills that run each spec phase with you.
Where this spec lives in Kiro, Spec Kit and OpenSpec
The template is tool-agnostic. Every spec tool splits it the same three ways, WHAT, HOW and the task list, under different file names. If you move between tools, this is the map:
Same spec, four homes
| Tool | Requirements (WHAT) | Design (HOW) | Tasks | Gate |
|---|---|---|---|---|
| Kiro | requirements.md in EARS (bugfix.md for bugs) | design.md | tasks.md | Approval between phases; Quick Spec skips the gates |
| Spec Kit 1.0.13 | specs/001-feature/spec.md, plus a repo-wide constitution.md | plan.md | tasks.md | One skill per phase; you run each |
| OpenSpec 1.14.1 | openspec/changes/<name>/proposal.md + a spec delta | design.md | tasks.md | Archive merges the delta into openspec/specs/ |
| Claude Code, no kit | spec/<feature>/requirements.md | design.md | tasks.md | The .status file; the agent reads it every session |
My run used the last row: three files and a .status, no tool installed. If you want that folder with the gates enforced by skills instead of discipline, claude-sdd-kit is the one I use in Claude Code. The deeper guides: what Kiro is, GitHub Spec Kit 1.0, OpenSpec from install to archive, and the three compared.
AGENTS.md is not the spec
AGENTS.md (or CLAUDE.md) holds what is true for every task in the repo: the commands, the conventions, the boundaries that never change. The spec holds what is true for one feature: its requirements, its Non-Goals, its acceptance checks. Put feature rules in AGENTS.md and every session pays for them in context, long after the feature shipped. Put repo rules in every spec and they drift apart. When a boundary shows up in three specs in a row, promote it to AGENTS.md.
Before you hand a spec to the agent
Spec readiness gate
- The Smart Kid Principle passes: someone with no context can build the right thing from this.If you'd have to explain anything verbally that isn't in the document, the document isn't done.
- Every functional requirement is in EARS format.If you wrote 'should be fast' or 'handle errors gracefully', find it and replace it.
- Non-Goals are explicit: at least 3 things you're not building.The absence of a Non-Goals section is a scope risk, not a clean spec.
- Validation rules have input/output example tables.Prose validation rules are almost always underspecified. Tables close it.
- All User Stories have testable acceptance criteria.If a criterion isn't independently testable, it's a vague goal, not a requirement.
- Stable IDs exist and are unique: US-001, FR-001, NFR-001, D-001.You'll reference these in design.md and tasks.md. Missing IDs break traceability.
- The Implementation FAQ covers the top 3 edge cases.At minimum: the deletion cascade, the conflicting-state scenario, and any access-control edge.
- Performance requirements have numbers, not adjectives.'Fast' is not a requirement. '500ms at p95 for lists up to 1,000 tasks' is.
- The spec ends with a 'Confirm before building' line.The agent restates the key requirements in its own words before typing code. If it misunderstood anything, you learn now, not after.
- The .status file says 'requirements:draft' until you've reviewed and approved.Draft is not approved. The agent must not proceed to design on a draft spec.
- Non-Functional Requirements cover performance, security, and accessibility.These are the three sections most consistently missing from first drafts.
- Boundaries are written in three tiers: Always, Ask first, Never.Never lists the edits you would revert in review. Ask first says what to do when nobody answers.
- Verification asks for evidence: the command and its output.An agent that only says 'all tests pass' hasn't shown you anything. Make pasting the output part of done.
FAQ
How long should a requirements.md be?
Long enough to prevent wrong assumptions, short enough to stay maintained. A typical production feature lands between 400 and 800 lines, including the template boilerplate.
If you're over 1,000 lines, ask whether this is one feature or two. If you're under 200, ask whether you've actually answered the hard questions, or just written the questions.
Do I need all three documents for every feature?
For a throwaway script or a two-hour fix, no. Just prompt and go. The overhead isn't worth it.
For anything that spans multiple sessions, involves real architecture choices, or handles data you can't easily rewrite, all three earn their keep. The design.md prevents the most expensive mistakes; the tasks.md prevents the most wasted implementation effort.
What's the difference between Non-Goals and Constraints?
Non-Goals are features you're choosing not to build in this version: 'no recurring tasks.' Constraints are things you have to work within: 'must use the existing database, no new services.'
Non-Goals protect scope. Constraints shape the solution space. Both belong in requirements, in separate sections.
Can I use this template with agents other than Claude Code?
Yes. The format is plain markdown. Any agent that can read files benefits from this structure: Cursor, Copilot, GPT-4o in a custom GPT, Gemini. The EARS syntax and stable IDs are model-agnostic.
The .status gate file is specific to the SDD workflow I use, but the documents themselves work with any capable agent.
My team writes specs in Confluence or Notion. Do I have to switch to markdown files?
Not strictly. The value is in the structure and the content, not the format. You can write a spec in Notion and paste it into the agent context at the start of each session.
The reason I use markdown files in the repo is traceability: the spec lives next to the code it governs, it's versioned in git alongside it, and the agent reads it directly without any copy-paste step. That last point matters more than it sounds. Friction is how specs get skipped.
How do I handle a requirement that changes mid-implementation?
Update requirements.md, add a change note with the date, set the .status back to 'requirements:draft', and re-approve before the agent continues.
The discipline is: never let the agent implement from a spec you haven't re-read since the change. A changed requirement that doesn't propagate to the design creates a contradiction between what the code does and what the spec says. Future you has to untangle it cold.
What if I don't know all the answers when writing the spec?
Write what you do know, and put the open questions explicitly in the Implementation FAQ section, marked as open, not answered. That's still better than silence, because the agent sees the question and knows to ask rather than guess.
Then resolve them before you approve the spec. An open question in an approved spec is a delayed bug.
What are EARS requirements?
EARS (Easy Approach to Requirements Syntax) is a way to write each requirement as one sentence with a fixed shape: an optional trigger or condition (WHEN, WHILE, IF, WHERE) followed by THE SYSTEM SHALL and the response. Alistair Mavin and colleagues developed it at Rolls-Royce; it was first published in 2009.
For an AI agent, the fixed shape removes the room to guess: every requirement names when it applies and what must happen. Kiro writes its requirements.md in EARS by default.
How long should I spend writing a spec?
I didn't time mine. The spec in my run was 151 lines of markdown across three files for one endpoint. The interview step is the shortcut: in a separate run it produced 12 questions in 13 seconds, and they covered every decision my spec had made. Answering them is most of the writing.
What the spec bought: 14 of 14 acceptance checks against 8 of 14 for a one-line prompt, for $0.021 more in agent cost.
How do I write a spec for existing code?
Same template, with two additions. Name the files the change starts from (the Commands section), and add a Non-Goal for every behavior that must not change. Kiro's bugfix specs make that explicit with a WHEN [condition] THEN the system SHALL CONTINUE TO [existing behavior] line.
Run the interview step first: the agent reads the repo before it asks, which is how it spotted the race in my test repo. For large legacy systems, the AI-DLC in brownfield guide on this site covers reverse-engineering the spec first.
Is AGENTS.md the same as a spec?
No. AGENTS.md (or CLAUDE.md) is loaded in every session and holds what is true for the whole repo: commands, conventions, permanent boundaries. A spec holds one feature: requirements, Non-Goals, acceptance checks. Keep feature rules out of AGENTS.md; they cost context in every session after the feature ships.
How do I check the agent followed the spec?
Write the acceptance checks before the build and run them yourself. In my run, 14 tests written before either build were the judge, and the agent never saw the test file. A suite you wrote is harder to game than one the agent wrote alongside the code.
Then ask for evidence, not claims: the test command and its output. Anthropic's guide adds a review step in a fresh subagent that checks the diff against the plan and reports gaps.
Does a spec still help with a strong model?
Yes, but not the way people expect. In my run the one-line prompt got the hard part right: no double charge under 50 concurrent retries. What it couldn't get right were the decisions only I could make: status codes, the expiry window, what a duplicate in flight receives.
A strong model cuts the bugs that come from misunderstanding. The decisions stay yours, and the spec is where you write them down.
Where to go next
A good spec takes 30-90 minutes to write for a typical feature. That time returns in the first implementation session: you spend it on problems that are actually hard, not on debugging misunderstood requirements.
Writing specs for a team instead of for yourself? Spec-Driven Development for teams covers the shared-spec workflow, and AI-DLC vs Spec-Driven Development is the next rung up. Specifying a change to legacy code? AI-DLC in brownfield starts by reverse-engineering what the system does today.
Free book · 169 pages · PDF + EPUB
Write specs that pass every check, not 8 of 14. The book walks one real project and leaves you requirements, design and tasks templates.
Get the free book